
A structural breakdown of the token feedback loop inside a single Agent task — what you see delivered is only the tip of the consumption iceberg.
Users see a 10,000-token deliverable — but the system may have burned through 400,000, or even 3,000,000 tokens to produce it. An unmetered Agent system is a reservoir with no floodgate. Using a typical Web3 project marketing campaign as the sample task, this study conducted a stage-by-stage structural estimation of token consumption across an Agent workflow, arriving at five findings that should reshape how enterprises think about AI cost.
First, users typically only see the tip of the iceberg above the waterline: behind a roughly 10,000-token marketing content package sits a single-Agent workflow with total consumption of approximately 390,000 tokens — delivered tokens account for just 1%–3% of total consumption, and what the user sees falls well short of the waterline. Second, the primary engine of amplification isn't generation itself, but the "context re-read tax" — with each step forward, the Agent must re-read its entire prior history, and the cumulative re-read volume across an N-step task scales approximately as N²/2, meaning amplification follows a quadratic law, not a linear one. Third, reflection and retries are the deepest hidden black hole: every round of "self-check → revise and rewrite" means a full re-read of context plus a full regeneration — three rounds of reflection cost roughly the same as redoing the task three times over. Fourth, multi-agent collaboration pushes the amplification factor from 30x to as high as 300x, because the orchestrator broadcasts context to every sub-agent, agents cross-validate and debate each other's outputs, and failed branches trigger full retries — collaboration doesn't divide the workload, it multiplies the context copies by N. Fifth, consumption is decoupled from headcount and scales super-linearly with task complexity — in the Agent era, token budgets can no longer be estimated using "headcount × usage frequency"; the only effective governance lever is metering down to the granularity of every single call, every single task.
From Linear Consumption to the Internal Feedback Loop: Defining the Amplification Effect
In the chatbot era, token consumption was linear: one user prompt, one model response, with the bill mapping one-to-one to conversation volume. The Agent era has completely rewritten this function. Once an Agent receives a task, it autonomously plans steps, retrieves reference material, calls tools, drafts content, self-reflects, revises and rewrites, and cross-validates — and the vast majority of this token consumption happens inside the system, invisible to the user from start to finish. Tokens circulate and combust repeatedly within the Agent's operational loop — this is the "loop-side" phenomenon this research refers to as the Token Amplification Effect.
The core metric of this effect is: Amplification Factor A = Total Task Token Consumption ÷ Final Delivered Tokens. Intuitively, this ratio tells you how many tokens the system burns behind the scenes for every single token of output the user receives. Chatbots run at an A value of roughly 1–2; our estimates show that Agent workflows start in the double digits, with multi-agent scenarios easily breaking into triple digits.
Why does this metric matter? Because it determines two things: first, the enterprise's real bill — for the identical requirement of "generate marketing content," the cost difference between A = 5 and A = 300 is a 60x gap; second, supply-side capacity planning — the "50 million tokens per day" threshold identified in prior cost research could be blown through in a single morning once an Agent system's A value runs unchecked. Put simply, an Agent isn't a more expensive chatbot — it's an entirely different species with a fundamentally different consumption structure. To evaluate its bill, you first have to dissect its loop.
(Methodology note: All figures in this report are bottom-up estimates based on public model specifications and typical workflow structures. Key assumptions are itemized in each section to illustrate the structure and order of magnitude of consumption — they are not audited, real-world measurements from any single system.)
Dissecting a Marketing Campaign Task: Where Did 390,000 Tokens Go
The sample task: feed a single content Agent roughly 25,000 tokens of project materials (whitepaper excerpts, official website copy, community FAQ), and request a complete marketing content package — one flagship post, two thread sequences, one long-form announcement, one event campaign brief, and six sets of image-generation prompts — totaling roughly 10,000 delivered tokens.
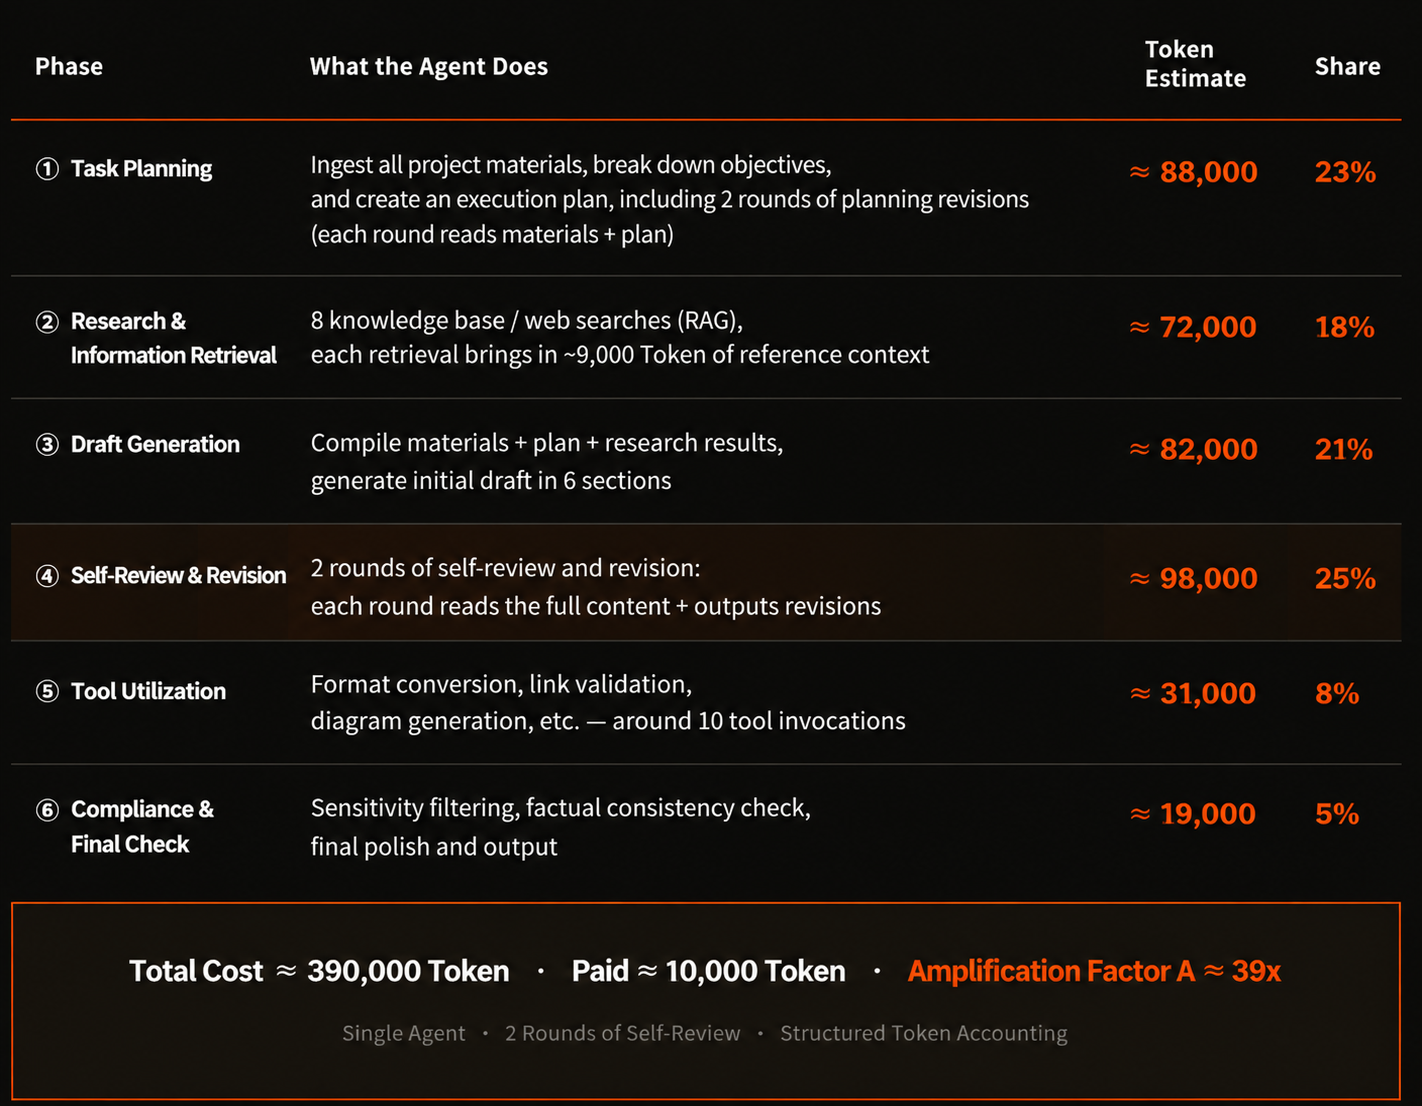
The stage-by-stage breakdown shows consumption concentrated across six phases: in the task-planning phase, the Agent reads in all project materials, breaks down objectives, and generates an execution plan through two rounds of plan revision, each requiring a full re-read of materials and plan — this step consumes roughly 88,000 tokens, or 23% of the total. In the retrieval-injection phase, eight rounds of knowledge-base/web retrieval (RAG) each inject roughly 9,000 tokens of reference material into the context, consuming roughly 72,000 tokens, or 18%. In the draft-generation phase, carrying the full context of materials, plan, and retrieval results, the Agent generates the content draft across six segments, consuming roughly 82,000 tokens, or 21%. In the reflection-and-rewrite phase, two rounds of self-review and revision each require a full re-read of context and a full revised output, consuming roughly 98,000 tokens, or 25% — the single largest line item across all six phases. In the tool-invocation phase, ten tool calls covering formatting, link validation, and image-prompt generation consume roughly 31,000 tokens of input/output, or 8%. In the compliance-and-final-review phase, sensitive-word filtering, fact-consistency checks, and final output consume roughly 19,000 tokens, or 5%.
Summed across all six phases, total consumption is approximately 390,000 tokens against roughly 10,000 delivered tokens — an amplification factor A of approximately 39x. Two details stand out from this breakdown: first, pure "generation" accounts for only about a fifth of consumption — roughly 80% goes toward reading, planning, retrieving, and revising; second, the single highest-share line item is reflection and rewriting — precisely the step that makes an Agent "accountable for the outcome" rather than a one-shot generator. Quality and consumption are, structurally, the same thing.
Three Engines of Amplification
Engine One: The Context Re-read Tax — the culprit behind the quadratic law. Large models have no persistent working memory — with every step forward, an Agent must re-read its entire prior history (materials, plans, retrieval results, previously generated content) as fresh input. If each step adds roughly L tokens of new context, then step K requires re-reading roughly K × L tokens, and the cumulative re-read volume across an N-step task scales approximately as N² × L ÷ 2 — doubling the step count quadruples the re-read tax. This explains a counter-intuitive phenomenon: the more finely a task is decomposed and the more "rigorous" the Agent becomes, the higher the per-unit-output cost may actually climb. Amplification grows quadratically while budget intuition assumes linear growth — and that gap between the two curves is exactly where costs spiral out of control.
Engine Two: The Reflection Loop — redoing the task N times over. Every round of "check → critique → rewrite" is a full context re-read plus a full regeneration. Estimates show each additional round of reflection adds roughly 25%–40% to total task consumption; an Agent running three rounds of reflection has, cost-structurally, redone the task three full times. Reflection buys delivery quality — but without metering, you have no idea how many multiples of the price you're paying for that quality.
Engine Three: Retrieval Injection — every query adds another layer. Every RAG retrieval call injects thousands of tokens of external material into the context, and that injected material gets re-read on every subsequent step — retrieval isn't a one-time expense, it's principal that keeps accruing interest. The more frequent the retrieval and the more generously it's injected, the higher the base for the re-read tax — the two engines feed each other in a positive-feedback loop.
Planning is burning tokens. Retrieval is burning tokens. Reflection is burning tokens. Re-reading is burning tokens — generation itself, ironically, is the cheapest action in the entire machine.
From 37x to 300x: The Multi-Agent Multiplier
A single Agent's 39x is only the starting point. Once a task is handed to a multi-agent system — an orchestrator directing multiple sub-agents across copywriting, imagery, review, and data — three multipliers kick in: context broadcasting (the orchestrator must replicate the task background to every sub-agent, copying context N times); cross-validation and debate (agents peer-review each other's outputs, with every review round requiring a full re-read); and failed-branch retries (if any sub-task fails, the associated branch is fully rerun). Collaboration doesn't divide consumption — it multiplies it.
Workflow complexity can be sorted into five tiers. At the base, L1 — Single-Turn Direct Output is the chatbot-style single-prompt/single-response scenario with no loop, carrying a typical amplification factor of 1–2x and total consumption of roughly 20,000 tokens against a 10,000-token delivery. L2 — Single-Agent Base Flow adds planning, retrieval, and generation without reflection, pushing the amplification factor to 8–15x and total consumption to roughly 100,000–150,000 tokens. L3 — Single-Agent Full Flow, the sample measured in this report, includes 2–3 rounds of reflection-and-rewrite plus tool invocation, reaching an amplification factor of 30–50x and total consumption of roughly 300,000–500,000 tokens. L4 — Multi-Agent Collaboration, an orchestrator plus 3–5 sub-agents running cross-validation, layers context broadcasting on top of review cycles, jumping the amplification factor to 80–150x and total consumption to roughly 800,000–1,500,000 tokens. L5 — Deep Research Mode, involving multi-round debate, large-scale retrieval, long-horizon reasoning, and failure retries, is an inference-time-compute-intensive scenario with an amplification factor of 300x or higher and total consumption starting at roughly 3,000,000 tokens.
Market signals corroborate these estimates: in June 2026, leading vendors formally abandoned "unlimited" subscription pricing for Agent products — once the A value can swing freely between L2 and L5, any flat monthly plan is effectively writing the opposing side a blank check. By the same logic, any enterprise budget model based on "headcount × frequency" has already failed structurally.
The real question was never "is the Agent expensive" — it's whether you know which tier your system is actually running at. L3 is productivity; an uncontrolled L5 is an incident. And "knowing which tier you're running at" is itself a piece of infrastructure capability — it requires consumption to be uniformly metered, attributed task-by-task, and visible in real time.
Reservoir and Floodgate: Metering Is the Only Form of Governance
The amplification effect cannot be "eliminated" — re-reading, reflection, and retrieval are precisely how Agents produce quality output. The only lever available is making every drop of consumption visible, attributable, and controllable. That requires shifting metering granularity from the "monthly invoice" down to "every single call, every single task, every single Agent."
This is exactly the engineering answer UniKey delivers through its AI Credits system. First, a unified unit of account: consumption across model calls, retrieval, tools, Agents, Skills, and Workflows all converges to a single unit — an official standardized denomination of 1U = 10,000 AI Credits — so that planning, retrieval, reflection, and generation, the combustion of every different engine, can for the first time be reconciled on a single ledger, turning hundreds of thousands of tokens of internal loop activity into one clear Credits statement. Second, task-level traceability: consumption detail can be attributed by task, by Agent, and by phase — letting you see exactly where every multiple of that 39x went, whether to planning, retrieval, or reflection, and how much L4's broadcast overhead versus L5's debate overhead each cost. Third, budget floodgates: quota, permissions, and usage controls at the team and project level require L5-tier consumption to request floodgate approval up front, rather than being reconciled after the fact on an invoice. Fourth, routing to reduce cost: multi-model intelligent routing directs re-reading and retrieval — the more "reflexive" workloads — toward lower-cost models currently undergoing technical deflation, reserving expensive reasoning-grade compute for the steps that genuinely require it, compressing the unit price of every multiple of amplification without sacrificing the underlying A-value structure. Fifth, settlement-grade auditing: every call, execution, and delivery is logged at the settlement layer, so consumption and contribution across multi-agent collaboration can be allocated, traced, and settled.
Operationally, this governance forms a complete closed loop on UniKey: top up AI Credits to obtain quota → allocate budget floodgates by team and project → Agents execute tasks while consumption is displayed in real time as itemized Credits → usage reports are reviewed at the task level to identify runaway L4/L5 workflows → orchestration gets optimized so the same deliverable is completed at a lower A value. The amplification effect goes from being an untracked mess to a governable operating metric that can be continuously compressed. For teams already handing marketing, community, and content work over to Agents, the day you plug into unified metering is the day the reservoir gets its floodgate.
An Agent system is a reservoir: upstream is the inflow governed by a quadratic law, and your budget is the reservoir's capacity. The amplification effect guarantees that inflow will always outpace intuition — and an unmetered Agent system is a reservoir with no floodgate.
Data note: All figures in this article are bottom-up structural estimates intended to illustrate the shape and order of magnitude of token consumption, not audited real-world measurements. The "loop-side" concept references publicly available industry research. Product details are subject to the vendor's latest official policy.

All Comments